Guide
Best AI Spend Management Tools for SaaS Teams in 2026
Ten tools compared for SaaS companies that sell AI features: which record cost per customer, which can refuse a call before it reaches the provider, and where each one fits.
This list is for software companies that sell AI features on a fixed subscription. Each customer pays the same price every month, but what they cost you in model calls can vary several times over from one customer to the next, and a single busy agent can turn a profitable account into a loss without anyone noticing until the invoice arrives. So the questions that matter are: which customers cost more than they pay, and what stops one customer or agent from running up the bill?
The short answer:
- To record AI cost per customer across providers, compare it with revenue where you share revenue data, and check customer or agent budgets before supported requests: Spendline (our product).
- To put AI costs into a company-wide cost platform alongside cloud: CloudZero, Vantage or Finout.
- To run your own gateway with budgets, for free: LiteLLM.
- For a managed gateway with prompt management and safety checks: Portkey.
- For a free dollar cap on traffic you already send through Cloudflare: Cloudflare AI Gateway.
- For tracing and evals: Langfuse.
- For a free safety net on one provider: OpenAI's and Anthropic's own spend limits.
We make Spendline and rank it first, so read the list with that in mind. Every claim about another product links to that vendor's own documentation or pricing page, checked on 3 October 2026. Where another tool is the better buy, we say so.
What to look for when you sell AI features
Most tools in this category can attach a customer ID to an AI call. Fewer turn that into something a finance team can act on. Four things separate them.
Cost recorded per customer, per call. Provider reports group usage by model, project or API key. Your application supplies the customer and workflow context needed to see cost per account. A gateway or proxy can record the customer on each request. A cost platform that starts from the provider bill has to allocate cost to customers afterwards, using rules or usage data you send it.
That cost next to what the customer pays. A customer tag tells you cost. Margin needs revenue too. This is the difference between a dashboard engineers use and a number finance can use in a pricing or renewal conversation.
A check before the call, shaped like your business. Only tools in the request path can refuse a call before the provider charges for it, and most of them decide from an estimate, so a long response can still cost more than expected. What matters for a SaaS company is the shape of those limits: each customer stays within its own allowance, the agents serving that customer share it, and the team running them stays within its overall budget. Several gateways can approximate this with overlapping rules. The difference is whether that structure comes built in for every customer or is maintained by hand, rule by rule.
A clear record of budget decisions. When a call is refused, the team needs to see which budget refused it and why, so the next decision about that customer is made on evidence rather than on a limit nobody remembers changing.
The table summarises what each vendor's own documentation described when we checked it. Where a cell says "not described", we did not find it in the documentation; that is not proof the product cannot do it, so ask the vendor.
| Tool | Customer cost | Revenue comparison | Refuses calls before the provider | Limits below project level | Price (vendor's published figure) |
|---|---|---|---|---|---|
| Spendline | Per routed call, from the customer ID your app sends | Where you share revenue data | Strict budgets, from a pre-call estimate | Org, team, agent and customer budgets | Guided pilot; paid terms agreed before you start |
| CloudZero | Allocated from usage data | Listed as a feature | Not described | Not described | On request |
| Vantage | Allocated from billing | Gross margin from a revenue metric; per customer not described | Not described | Not described | Free up to $2,500 spend |
| Finout | Allocated by tags | Not described | Not described | Alerts | On request |
| LiteLLM | Per call | Not described | Yes, with pre-call reservations | Teams nest; customers separate | Free, self-hosted |
| Portkey | Per call | Not described | Budget policies (Enterprise and select Pro) | Workspace and key | Free tier; $49/mo |
| Cloudflare AI Gateway | Per call | Not described | Yes | Up to 20 overlapping rules | Free |
| Langfuse | Per trace | Not described | Not described | Not described | Free tier; $29/mo |
| Helicone | Per call | Not described | Cost-based rate limit per window | Per user or property | Free tier; $79/mo |
| OpenAI, Anthropic | By project or workspace | No | Whole project or workspace | Org, project, workspace | Free |
1. Spendline
Best for SaaS companies that want AI cost per customer and a budget check on a customer or agent before supported requests reach the provider.
Spendline sits between your application and your model providers. Your engineer changes the endpoint for a supported route and adds headers naming the customer, agent and team. Spendline prices and records each routed call against them across ten providers: OpenAI, Anthropic, Google Gemini, xAI, Mistral, DeepSeek, Alibaba Qwen, Together AI, Fireworks AI and Groq. Supported request shapes are chat completions for OpenAI-compatible providers, Anthropic Messages, and non-streaming OpenAI Responses. Enter or import each customer's monthly revenue as a CSV, and the customer view compares revenue with attributed AI cost over the same period, where you share revenue data. Other delivery costs are not included.
Budgets nest from the company down to a team, an agent and a single customer. Spendline checks configured budgets before forwarding supported requests. Strict budgets reject requests whose estimated cost would exceed a limit, with an HTTP 402. Actual response cost can differ from the estimate. Budgets that are not strict record spend and alert without refusing calls. Threshold alerts go to a Slack or Discord webhook at 50, 80, 90, 100 and 120% of each configured budget. Separately, reroute rules can send chosen calls to a different model. Every routed call and every refusal is recorded, and corrections are added as new entries, never edits.
An example. This one is illustrative. A customer pays you $600 a month. By the 20th of a 30-day month its AI calls have cost $420. Most of it came from one research agent whose $300 monthly budget has reached $270.
- See it. Where you share revenue data, Spendline compares that cost with the revenue for the same 20 days, about $400, so the customer view shows the account at roughly minus 5% margin after AI cost. Opening it shows the research agent is where the money went, and which model it is using.
- Contain it. The 80% and 90% alerts on the agent's budget have already gone to the team's Slack channel. The budget is strict, so when the next call's estimated cost would take the agent past $300, that call is refused before it reaches the provider, while the customer's other agents keep working. The refusal is recorded with the budget that refused it.
- Explain it. Because each call was recorded against the customer and agent when it happened, you have the per-agent, per-model history for a pricing or renewal conversation with that customer, without rebuilding it from logs.
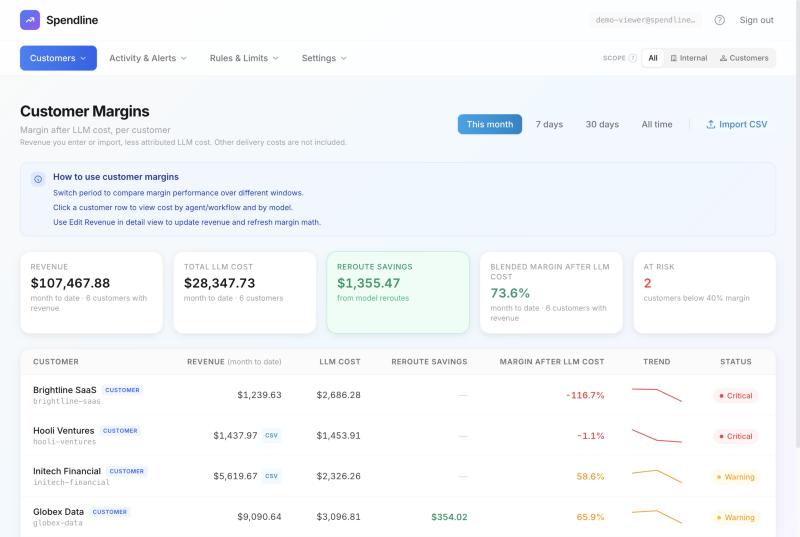
The customer margins view in Spendline's sample account. Sample data, not real customers.
Where it falls short: it does no prompt tracing or evals, so teams that need those pair it with something like Langfuse. It runs as a hosted proxy, not self-hosted. It covers only traffic routed through it: calls sent directly to a provider, including any direct-provider fallback, and unsupported API shapes such as embeddings, images and audio are outside its controls and records. Its budget check prices each call from an estimate of the output, so one unusually long response can settle above a cap. Margin here means revenue minus attributed AI cost, not full gross margin. And it is a young company.
Commercial terms: start with a guided 30-day free pilot on live production traffic. The 30 days start when your traffic flows through Spendline, not at sign-up. We agree the scope, success criteria and paid terms before you start. There is no Spendline subscription fee during the pilot; your model-provider charges still apply.
2. CloudZero
Best for unit cost across cloud and AI at a larger company.
CloudZero ingests Anthropic and OpenAI cost data next to AWS, Azure and GCP, and calculates cost per customer from usage data you stream into it. Its cost-per-customer page lists margin per customer as a feature. Pricing is a single subscription quoted to your environment.
It works from billing and usage data, so it reports and alerts rather than refusing individual calls. If your AI cost is a small part of a large cloud bill, it is likely a better fit than anything else here.
3. Vantage
Best for putting AI bills next to cloud bills on a small budget.
Vantage connects to OpenAI and Anthropic with admin API keys, refreshes daily, and reports AI spend alongside AWS, Azure, GCP and more than 30 other providers. It can calculate gross margin from a revenue metric you supply, though its docs do not show that broken down by customer, and OpenAI cost arrives split by project and API key. Budgets send alerts. The Starter plan is free up to $2,500 of tracked spend, Pro is $30 a month up to $7,500, and Business is $200 a month up to $20,000.
4. Finout
Best for allocating AI spend across the company without code changes.
Finout brings OpenAI, Anthropic, Bedrock and Vertex costs into one bill with cloud and Kubernetes spend, and splits them by team, feature or customer with tagging rules. Its Financial Plans nest, but they track and alert rather than block. Pricing is a yearly fee based on committed spend, quoted, not published.
5. LiteLLM
Best if you want to run the gateway yourself, for free.
LiteLLM is an open-source proxy for more than 100 model APIs. Its budgets are enforced before the call, at the global, team, team member, user, key and end-customer level, and it reserves each call's estimated cost first so concurrent requests cannot jointly overshoot. Team and team-member budgets nest. Customer budgets apply across the whole deployment, outside any team, budgets need its database to work, and model-specific budgets need an Enterprise licence. There is no margin view, and you run it yourself.
6. Portkey
Best for a managed gateway that also handles prompts and safety checks.
Portkey combines routing, fallbacks, observability, prompt management and safety checks, with an open-source gateway you can host. Its budget policies reject requests before they are forwarded, at the workspace or key level and through usage policies, and are available to Enterprise and select Pro customers. The Production plan is $49 a month for 100,000 logged requests.
7. Cloudflare AI Gateway
Best free dollar cap if your traffic already runs through Cloudflare.
AI Gateway added spend limits on 5 June 2026, launched as an open beta. Each rule is scoped by model, provider or custom metadata over a fixed or sliding window, and every matching rule is checked before the call, so you can layer a per-user limit under a gateway-wide one. Any of them can block a call with an HTTP 429. Its docs allow up to 20 rules per gateway and note that concurrent bursts can briefly exceed a limit. That suits a handful of broad limits well; a separate allowance for each of hundreds of customers would need a rule each.
8. Langfuse
Best for engineers who need tracing and evals.
Langfuse is open source, self-hostable and strong on tracing, prompt versions and evaluation. It calculates cost per call from its own model price list and can alert on cost to Slack, a webhook or GitHub Actions, but it does not block calls. Core is $29 a month. Plenty of teams run it alongside a gateway.
9. Helicone
Observability and a gateway, with a cost-based rate limit. Check its current status before you commit.
Helicone combines observability with a gateway, and its custom rate limits can cap spend in cents per rolling window, for example one dollar an hour per user. Mintlify announced it was acquiring Helicone in March 2026. When we checked on 23 October 2026, Helicone's homepage said Helicone is no longer part of Mintlify, with details to follow, so ask the team directly about its roadmap and support. Pro is $79 a month.
10. OpenAI's and Anthropic's own limits
Best free safety net. Set these whatever else you use.
OpenAI added self-service spend limits on 22 July 2026, for the organisation or a project. Requests over the cap fail with a 429, and OpenAI notes enforcement is not instantaneous. Anthropic has a monthly spend limit for the organisation, and workspaces can be capped lower than it.
Each covers one provider, and a cap stops the whole project or workspace, including the customers that did nothing wrong.
FAQ
How do I find out which customers cost more in AI than they pay? Record the customer on each model call when the call is made, then compare that cost with what each customer pays over the same period. Provider reports group usage by model, project or API key, so your application has to supply the customer context. Spendline records the customer your application sends on each routed call and, where you share revenue data, compares it with that customer's revenue; cost platforms like CloudZero allocate cost from usage data you send them.
Can I stop one customer or agent from running up the bill without cutting everyone off? Only with a tool in the request path that supports limits below the project level. Provider caps stop the whole project. Spendline, LiteLLM, Portkey and Cloudflare AI Gateway can each limit narrower scopes; Spendline lets a customer budget sit inside team and company budgets, and checks all of them before forwarding a supported request.
Can a FinOps platform stop AI overspend? Not on its own. CloudZero, Vantage and Finout work from billing and usage data and alert on it. They do not sit in the request path, so refusing an individual call needs a gateway or proxy.
Is there a free option? Yes: OpenAI's and Anthropic's spend limits, Cloudflare AI Gateway's spend limits, a self-hosted LiteLLM, and Vantage's free tier up to $2,500 of tracked spend. None of them compares AI cost with revenue per customer in their documentation.
Sources and method
Written by the Spendline team. Spendline makes one of the products listed. Every capability and price for another product comes from the vendor's own documentation, pricing page or announcement, linked where it is cited and checked on 3 October 2026; Helicone's status was re-checked on 23 October 2026. Where a vendor's docs did not settle a point, we say what the docs show rather than guess, and a gap in the documentation is not proof a product lacks the feature. Spendline's own capabilities were checked against the product on 23 October 2026. The example is illustrative, and the screenshot comes from our sample account. This category changes month to month. If we have described a product wrongly, email fida@spendline.ai and we will correct it.
See what this would look like in your product.
Start with a guided 30-day free pilot on live production traffic. The 30 days start when your traffic flows through Spendline, not at sign-up. We agree the scope, success criteria and paid terms before you start. There is no Spendline subscription fee during the pilot; your model-provider charges still apply.
Prefer email? fida@spendline.ai