Guide
AI Gateway, LLM Observability, or AI Spend Governance: What Each Layer Actually Does
What AI gateways, LLM observability, and spend governance each do, where they overlap, and how the three layers stack together.
If you are responsible for AI cost at your company in 2026, you are probably looking at a tool category that did not exist three years ago and is already fragmented into at least three sub-categories that get conflated in nearly every blog post and pitch deck.
There is the AI gateway category - LiteLLM, Portkey, OpenRouter - which makes it easier to call multiple providers behind a unified API. There is the LLM observability category - Helicone, Langfuse, Langsmith, OpenLLMetry - which tells engineering teams what is happening inside their LLM calls. And there is the emerging AI spend governance category - which puts the finance team in control of allocation, budgets, gross margin, and the close.
These categories are not competitors. They are layers in a stack. But because they all touch LLM API traffic and all claim "cost visibility" in their marketing, buyers routinely conclude they need to pick one - and end up with a tool that solves a different problem than the one they had.
This guide is the honest map. What each layer does, what each layer does not do, when you adopt which, and how they stack together. We sell software in the third category and have no interest in pretending the first two do not exist; we work better when they are present.
The three layers, in one sentence each
AI gateway: makes it easier for engineering to call multiple LLM providers from one place, with retries, fallbacks, and key management.
LLM observability: gives engineering visibility into what each LLM call is doing - latency, errors, prompts, completions, traces, evals.
AI spend governance: gives finance control over how AI spend is allocated, budgeted, and reconciled across customers, features, and cost centers.
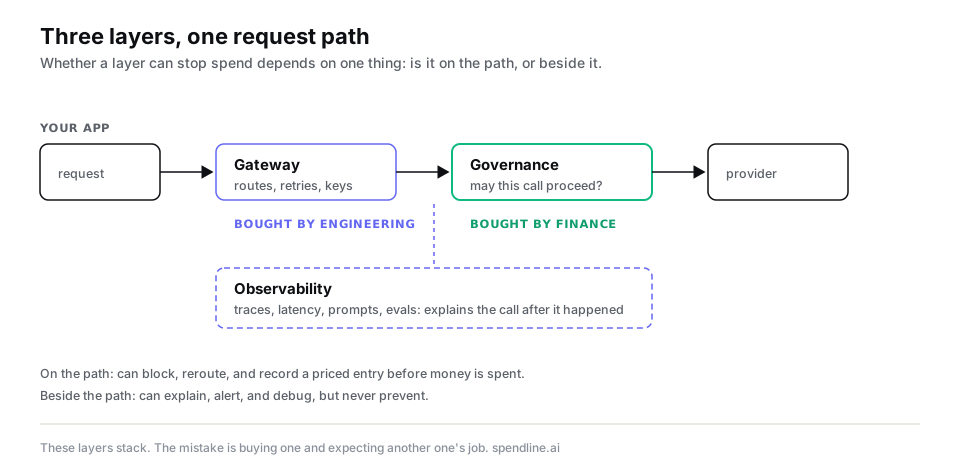
The verbs matter. Gateway makes it easier. Observability gives visibility. Governance gives control. Each verb maps to a different team, a different decision, and a different product surface.
The structural difference is simpler than the marketing suggests: a layer that sits on the request path can refuse a call before money is spent, and a layer that sits beside it can only explain the call afterwards.
What an AI gateway does
A gateway is engineering infrastructure. It sits between your application and one or more LLM providers and abstracts away the differences. The shape of the value:
- Unified API: call OpenAI, Anthropic, Google, Mistral, xAI through one SDK or one base URL
- Retries and fallbacks: if the primary provider is down or rate-limited, route to a backup automatically
- Key management: keep provider keys in one place, rotate them, scope them per environment
- Caching: deduplicate identical prompts to save tokens
- Some routing logic: cheap-model-first, premium-model-on-fallback, regional routing
The buyer is engineering. The benefit is operational simplicity and reduced vendor lock-in. LiteLLM, Portkey, OpenRouter, AWS Bedrock, Cloudflare AI Gateway are all in this category. They differ in deployment model (self-hosted vs. SaaS), routing sophistication, and ergonomics, but they are solving the same problem.
Gateways differ a lot here, so check the specific product rather than the category:
- Customer attribution. Most gateways record a user or metadata field you pass. Whether that becomes a paying-account view, and whether anything reports how much traffic is missing it, varies by product.
- Budgets. Some gateways enforce dollar budgets before the call. LiteLLM, for example, documents budgets for keys, users, teams and end customers, with pre-call reservations. Others offer only request-rate limits, which are not the same thing as a dollar budget.
- Revenue comparison. A gateway has cost and request data. It does not usually hold your revenue per customer or your cost classification policy.
If you have a gateway, check what its budgets and reports already answer before adding anything.
What LLM observability does
Observability is engineering tooling for understanding what is happening inside LLM calls. The value:
- Trace view: see the full path of a request through prompts, tools, sub-agents, retries
- Latency and error tracking: which models are slow, which calls fail, where the time goes
- Prompt and completion logging: the actual text in and out, so you can debug quality issues
- Eval framework: score model outputs against test cases, catch regressions
- Token-level metrics: input/output tokens, cost in dollars, attached to each call
- Some user/session tracking: who made the call, in which session
The buyer is engineering - typically the team building the AI feature, not the platform team. Helicone, Langfuse, Langsmith, Arize, LangWatch, Phoenix, OpenLLMetry are in this category, with significant variation in self-hosted vs. cloud, open-source vs. commercial, and depth of evaluation tooling.
What observability is not built to do:
- Allocation by business dimension. Observability tools track "user" and "session" - but "user" usually means the end-user of your product, not the paying customer whose contract attributes the cost. If a single paying customer has 50 users, observability does not roll those up to the customer level by default.
- Budget enforcement in the request path. Observability usually receives traces beside the request rather than in it, so it can alert on spend but is not positioned to refuse a call. Some products in this category also ship a gateway with limits; check the specific product.
- Period close. Observability is event-stream-oriented; finance needs period-locked snapshots with reconciliation against provider invoices, an adjustment ledger, and an audit trail. (See The AI month close for what this involves.)
- COGS classification policy. Observability stores tokens and dollars. The decision of whether a particular workload is COGS or R&D is made elsewhere. (See AI COGS vs R&D.)
If you have observability, your engineering team can debug AI quality issues and your platform team can see latency trends. Your finance team still does not have a number they can sign off on.
What AI spend governance does
This is the newest category, and the one most often conflated with the other two. Governance is finance and operations tooling for controlling how AI spend is allocated, budgeted, and reconciled. What products in it typically aim to provide:
- Per-customer cost attribution, as a first-class concept rather than an optional tag
- Budgets at several levels (for example org, team, agent and customer) checked before a request is forwarded
- Attribution completeness - how much spend is properly tagged, with the gap surfaced
- Month-end records that finance can compare with provider invoices, with corrections recorded as new entries
- Cost against revenue per customer, from request-level cost data and a revenue input
The buyer is usually finance and engineering together. Spendline is in this category. Some gateway, observability and cloud-cost vendors are extending into this space, with varying depth.
What governance is not built to do:
- Replace your gateway. If your engineering team needs a multi-provider abstraction layer with retries and fallbacks, governance tools either work alongside one or include a thin proxy for the routes they support.
- Replace your observability tool. Governance does not usually provide trace views, prompt-level debugging, or eval frameworks.
Comparing products, not categories
A tick-and-cross grid by category is misleading here, because individual products cross the lines. Ask these questions of each tool you already run, with its own documentation open:
| Question | What to check |
|---|---|
| Does it record the paying customer on each call? | Whether the field is the account or the end user, and whether it reports untagged traffic. |
| Can it refuse a call before the provider is billed? | Dollar budgets versus request-rate limits; which scopes; whether it reserves estimated cost for concurrent calls. |
| What happens to a long response? | Whether the pre-call check uses an estimate, and whether actual cost can exceed it. |
| Can it compare cost with revenue per customer? | Where revenue comes from and whether periods match. |
| What does finance get at month end? | An export, a ledger with corrections as new rows, a closed period, a comparison with the invoice total. |
| What traffic does it not see? | Direct-to-provider paths, fallbacks and unsupported API shapes. |
For Spendline the answers are in the section below and in the integration guide.
When to adopt which
There is no spend threshold at which a particular tool becomes mandatory. The signal is the question you cannot answer:
- Provider outages or several providers to manage. A gateway.
- Quality, latency or debugging problems. Observability.
- Finance cannot say what an account costs, or an agent can overspend with nothing checking it. First check whether your gateway's budgets and reports answer it. If they do not, a governance layer is worth evaluating.
Many small teams need none of these yet: the provider's own reports plus a customer ID logged in application code can be enough.
The stacking pattern
The clean architecture, when all three layers are present:
[ Application ]
      │
      ▼
[ AI Gateway ]   ← multi-provider abstraction, retries, fallbacks
      │
      ▼
[ Governance Proxy ]   ← captures cost, attribution, budget gates
      │
      ▼
[ Provider (OpenAI / Anthropic / ...) ]

[ Observability ]   ← receives async traces from app or gateway
A few notes on this pattern:
- Whether a governance proxy can sit in front of or behind your gateway depends on the request shapes each supports, so check compatibility first. In front captures spend before any routing logic, which is cleaner for attribution. Behind captures spend per actual provider call, which is cleaner for reconciliation against provider invoices. Either is defensible.
- Observability is usually side-channel, not in-line. Observability tools typically receive traces as async events, not as a synchronous proxy. This matters because adding observability does not add latency; adding a gateway or governance proxy can.
- Some tools collapse layers. Several vendors offer "gateway + observability" or "gateway + budgets" in one product, which means one fewer hop and one fewer vendor. Judge the specific capabilities rather than assuming a bundle is weaker.
What "good" looks like
A team with the full stack working well has these properties:
- Engineering can debug an AI quality issue in under an hour - observability gives them the trace.
- The platform team can swap providers without an application code change - gateway abstracts the API.
- Finance can see AI cost per customer, monthly, and compare it with revenue without a project.
- The board reporting includes AI spend with an allocation method, not "AI services" as a single number.
- Budgets are checked before the next provider call for the scopes that matter, and the team knows which traffic is outside those checks.
- Month close includes AI spend on the same calendar as every other cost line. (See The AI month close.)
Which tools deliver those properties is a product question, not a category one.
How Spendline does this
Spendline is a hosted proxy in the third layer. It is not an observability tool: it does not trace prompts or evaluate outputs, and it can sit alongside Langfuse, LangSmith or Helicone. Spendline routes supported AI requests, records attributed costs and applies configured controls. It covers traffic actually routed through it.
Concretely: your application supplies customer, agent and cost-centre labels per request; Spendline records them with each call in an append-only ledger across ten providers on the supported request shapes (chat completions for OpenAI-compatible providers, Anthropic Messages, non-streaming OpenAI Responses). Spendline checks configured budgets before forwarding supported requests. Strict budgets reject requests whose estimated cost would exceed a limit. Actual response cost can differ from the estimate. Where you share revenue data, it compares customer revenue with attributed AI cost over the same period; other delivery costs are not included. An owner can close a month and compare a provider invoice total with it, which records any difference as one adjustment. Spendline does not classify spend as COGS or R&D.
We work alongside LiteLLM, Portkey, Helicone, Langfuse, Langsmith and others. If your current gateway and reporting already answer your questions, you may not need another product. Integration details are in the integration guide.
FAQ
What is the difference between an AI gateway and LLM observability? A gateway makes it easier to call multiple providers from one place: retries, fallbacks, key management, caching. Observability makes what happens inside those calls visible: traces, latency, errors, prompts, evals. Both are bought by engineering.
What does governance add that observability does not? A finance view of the same traffic: attribution to the paying customer, budgets checked before provider calls, an untagged-spend measure, and month-end records finance can reconcile. Some gateways already cover part of this, so compare products rather than categories.
Do we need all three layers? Rarely at once. Most teams add a gateway or observability first because engineering feels the pain first, then add governance when AI spend becomes material. They stack rather than compete.
Can an observability tool do per-customer attribution? Partially, through tags. The gap is that it models the end user or session rather than the paying account, and treats tagging as optional, so nothing catches a code path that forgets the identifier.
Which should we buy first? Whichever answers the question you cannot answer today. Provider sprawl and outages point to a gateway; quality and debugging point to observability; "what does each customer cost against what they pay" and "what checks a runaway agent" point to governance, after checking what your existing gateway already does.
Sources and method
Written by the Spendline team, plus each vendor's public documentation for the capability descriptions (LiteLLM, Portkey, OpenRouter, Cloudflare AI Gateway and AWS Bedrock for the gateway layer; Helicone, Langfuse, LangSmith, Arize and OpenLLMetry for observability). The category boundaries and the comparison questions are our framework rather than an industry standard, and several vendors are actively extending across these lines, so treat the matrix as a snapshot of intent and current focus rather than a permanent verdict. Capabilities change: if we have described a tool unfairly or out of date, write to fida@spendline.ai and we will correct it. Related reading: tracking cost per customer, the AI month close, and what FOCUS 1.4 standardizes. Spendline's own capabilities, and LiteLLM's budget documentation, were checked on 23 October 2026.
See what this would look like in your product.
Start with a guided 30-day free pilot on live production traffic. The 30 days start when your traffic flows through Spendline, not at sign-up. We agree the scope, success criteria and paid terms before you start. There is no Spendline subscription fee during the pilot; your model-provider charges still apply.
Prefer email? fida@spendline.ai