Guide
How to Track LLM Costs Per Customer
How to tag, meter, price and reconcile LLM requests so you can calculate AI cost by customer, and what a proxy does and does not cover.
The short answer: tag every LLM request with a customer_id set server-side, meter all routed calls at a single choke point (a proxy or a wrapped client) and know which paths bypass it, price each request from token counts at the moment it happens, and keep the result as an append-only ledger you can roll up by customer and reconcile against the provider invoice. Each of those clauses carries weight, and skipping any one of them is how teams end up with numbers finance won't sign.
Most companies are far from this. In CloudZero's State of AI Costs research, 57% of surveyed companies still track AI costs manually in spreadsheets, and 15% have no formal cost tracking at all. LLM cost tracking at the customer level is what turns an AI bill into AI unit economics: the ability to answer "which customers are profitable?"
Why provider invoices can't show customer cost
Provider reports group usage by model, project or API key. Your application supplies the customer and workflow context needed to see cost per account. The provider view answers "what did we buy?" It cannot answer "who caused it?" And in a multi-tenant product, who caused it is the dimension that maps to revenue. Two customers on identical plans can differ by 10x in inference cost; averaged into a per-model number, both look fine. Per-customer cost allocation has to happen on your side of the API call, because only your systems know which customer a request belongs to.
The metadata contract
Customer-level cost attribution is a data contract, not a dashboard. Every request that reaches a model must carry, at minimum:
customer_id: the paying account (the org, not the end user). This is the join key to revenue.featureorworkflow: the product surface (chat,summarize,agent_research). Low-cardinality, safe to chart and alert on.agent_run_id: the user-initiated action that groups calls. One agent task can fan out into dozens or hundreds of model calls; without a run ID, a $4 agent run looks like 200 unrelated $0.02 requests.
Three rules make the contract hold:
- Set IDs server-side. Set customer IDs on your server from authenticated request context. A
customer_idaccepted from the client is a spoofable billing input, and no metering layer can tell a wrong ID from a right one. Timestamps are a separate question: the server's clock should decide which day and month a cost lands in, or your budget windows and month-end numbers drift. A server timestamp fixes the time, not the customer. - Meter all calls, not a sample. Sampling is fine for latency traces; it is wrong for money. If 5% of calls bypass the metering point, your per-customer numbers are estimates with an unknown error bar.
- Capture the token detail that pricing needs. Providers bill cached input at different rates than fresh input, and cache writes differently again. If you log only total input tokens, your computed cost will drift away from the invoice and you will discover it at month end.
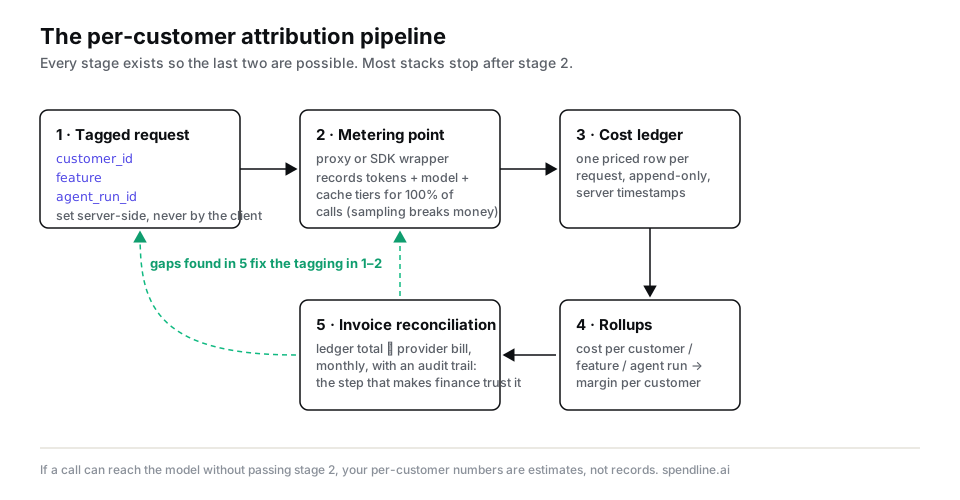
What this looks like in code
With an in-path setup, the integration is a base URL change plus the metadata headers. Using the OpenAI SDK against Spendline's chat completions endpoint, with the stable Spendline key in the client configuration and the customer set per request from your server's own request context:
import OpenAI from "openai";

const client = new OpenAI({
  baseURL: "https://www.spendline.ai/v1",
  apiKey: process.env.OPENAI_API_KEY,
  defaultHeaders: {
    "x-spendline-key": process.env.SPENDLINE_API_KEY,
  },
});

// account comes from your authenticated session, never from the browser.
const response = await client.chat.completions.create(
  { model: "gpt-5.2", messages },
  {
    headers: {
      "x-customer-id": account.id,              // the paying account, per request
      "x-agent-id": "support-summarizer",       // one stable value per agent or feature
      "x-workflow-id": run.id,                  // groups this run's calls
      "x-spendline-tags": JSON.stringify({ cost_center: "support" }),
    },
  }
);
Do not put x-customer-id in the client's default headers: every call would then be attributed to one customer. The same pattern applies with a self-hosted proxy or an SDK wrapper; what matters is that the identifiers ride with each request. Each call then lands in the ledger as one priced, attributed record:
{
  "created_at": "2026-08-04T09:12:44Z",
  "model": "claude-sonnet-4-5",
  "customer_id": "acct_4821",
  "agent_id": "support-summarizer",
  "workflow_id": "run_9f3c",
  "input_tokens": 2000,
  "cached_input_tokens": 0,
  "output_tokens": 600,
  "cost_usd": 0.015
}
And the question "what does each customer cost us?" becomes a one-liner instead of a reconstruction project:
SELECT customer_id, SUM(cost_usd) AS ai_cost
FROM ai_calls
WHERE created_at >= '2026-08-01' AND created_at < '2026-09-01'
GROUP BY customer_id
ORDER BY ai_cost DESC;
The cost math, and why rates need versioning
The full per-request calculation covers every meter the provider bills:
cost = (uncached_input_tokens × input_rate)
     + (cache_read_tokens     × cache_read_rate)
     + (cache_write_tokens    × cache_write_rate)
     + (output_tokens         × output_rate)
     + other provider-specific meters (batch, reasoning, regional)
A simplified worked example, using Claude Sonnet 4.5 list rates ($3 per million input tokens, $15 per million output, per Anthropic's published pricing) as a stable illustration rather than a current-flagship quote:
2,000 input tokens  × $3 / 1M  = $0.0060
  600 output tokens × $15 / 1M = $0.0090
                     cost/request ≈ $0.015
At 50 requests per customer per day, that's roughly $22.50 per customer per month. That is the kind of number you want per customer, from records, not divided out of an invoice. Prices change with little notice, differ per model tier, and sometimes carry introductory or regional adjustments, so the rate table itself needs a source of truth with effective dates; hard-coding prices into application code is how computed cost quietly diverges from the bill. Current per-model rates and the multipliers stacked on top of them (cache tiers, batch, reasoning tokens) are broken down in our guide to Anthropic API pricing.
Cost per customer is then the sum over the period, and gross margin per customer follows once revenue is mapped in. Mapping that revenue side correctly is its own exercise, worked end to end in how to calculate AI gross margin by customer; the wider framework and benchmarks are in our unit economics guide.
Three ways to implement it
There are three honest routes, and the right one depends on what you need the numbers for.
| DIY tagging + warehouse | Observability SDK | In-path governance proxy | |
|---|---|---|---|
| How it works | Log token counts + IDs yourself, price in SQL/dbt | Wrap your client library; platform prices each trace | Point your base URL at a proxy; it meters everything routed through it |
| Coverage | Only what you remember to instrument | Only code using the wrapper | Calls routed through it, on the API shapes it supports; direct-to-provider paths are outside it |
| Engineering effort | Highest, ongoing | Low per service, per-codebase | Base URL change, plus metadata injection for full attribution |
| Can it enforce (block/cap)? | No | Generally no; it observes | Yes, for routed calls; budgets checked before the request is forwarded, from an estimate |
| Finance-ready (reconciliation, immutable ledger) | If you build it | Rarely the focus | The point of the category |
Tools like Langfuse and Braintrust are strong in the observability lane: they exist primarily to debug, trace, and evaluate LLM behavior, with cost as one attribute of a trace (the alternatives in that lane, and where they stop, are compared in Langfuse alternatives). LiteLLM is a popular open-source proxy with spend tracking if you want to run the in-path route yourself. A governance proxy like Spendline is a managed version of that third route, adding budget checks before the provider call, an append-only ledger, and customer revenue comparison where you share revenue data. (Where each layer stops is mapped in gateway vs. observability vs. governance.)
The practical test: if a call can reach the model without passing your metering point, that call is missing from your per-customer numbers. List those paths, and compare your ledger total with the provider invoice to see how large the gap is.
From tracking to control and close
Attribution is the foundation, not the finish line. Once every request is a priced, attributed record, two things become possible that aren't otherwise:
- Enforcement. Budgets per customer, team, or agent that are checked before the request is forwarded, not only alerts after the spend happened. A runaway agent loop is an in-flight problem; a weekly cost review cannot catch it in time, and the controls that stop a single run work on the run ID rather than the month. The scopes, the actions available when a cap is hit, and the concurrency trap are covered in LLM budget enforcement.
- The finance loop. Monthly reconciliation of your ledger total against the provider invoice, investigation of any gap, and a close that locks the period. A persistent reconciliation gap usually points to incomplete token-type capture, stale rate tables, side-door traffic, retries, or provider-specific pricing adjustments. The workflow is described in The AI month close, and the invoice comparison itself is worked line by line in how to reconcile OpenAI and Anthropic invoices.
Common failure modes
- Client-supplied attribution. IDs or timestamps trusted from the browser/SDK caller: spoofable. A wrong customer ID is recorded as faithfully as a right one.
- The side-door path. A batch job, cron script, new microservice, or a fallback that retries the provider directly when the proxy is unreachable never appears in your numbers. Metering at the network path narrows this, but only for traffic that actually takes that path.
- Missing labels. A routed call with no customer ID is still priced and recorded, but it lands in an unattributed bucket. Track the unattributed share, and give genuine internal jobs a stable synthetic ID such as
internal:nightly-reindex. - Cached tokens priced wrong. One common cause of invoice divergence is cache reads and writes being priced at the fresh-input rate, or not captured as separate fields at all.
- Agent fan-out without a run ID. Per-request numbers look healthy while a single user action quietly costs dollars.
- Mutable records. If cost rows can be edited in place, reconciliation can't prove anything; corrections should be new rows.
How Spendline does this
Spendline is a managed in-path route. Point a supported route's base URL at Spendline and send x-customer-id per request, plus x-agent-id and x-spendline-tags for agent and cost centre. Spendline records the supplied customer ID and server time with each routed call, prices it, and writes it to an append-only ledger. One ledger covers OpenAI, Anthropic and eight other providers on the supported request shapes: chat completions for OpenAI-compatible providers, Anthropic Messages, and non-streaming OpenAI Responses. Embeddings, images, audio and Google's native generateContent API are not supported, and calls sent directly to a provider are outside Spendline's records. Where you share revenue data, Spendline compares each customer's revenue with attributed AI cost over the same period. Other delivery costs are not included.
The code sample earlier in this guide shows the request-level pattern. The integration guide lists the supported routes, their limits and how to check that the right customer receives the cost record.
FAQ
Can OpenAI or Anthropic show cost per customer? Not on their own. Provider reports group usage by model, project or API key. Your application supplies the customer and workflow context needed to see cost per account, via request tagging.
What metadata should every LLM request contain?
A customer_id, a feature or workflow name, and an agent run ID, all set server-side. That trio supports per-customer cost, per-feature economics, and per-run agent accounting.
Do you need an LLM proxy to track costs accurately? Not strictly. Wrappers and DIY logging work if every call path uses them. A proxy meters what is routed through it and can check budgets before a request reaches the provider, but calls sent directly to the provider, and API shapes it does not support, are outside it.
How should cached tokens be priced? At the provider's cache rates: on Anthropic models, cache reads run about a tenth of the base input price and cache writes carry a premium. Log cached and fresh counts separately.
How do you reconcile calculated LLM costs with provider invoices? Sum the ledger by provider for the billing period, compare to each invoice, investigate persistent gaps (token-type capture, stale rates, side-door traffic, retries, pricing adjustments), post corrections as new records, and lock the period.
Sources and method
Written by the Spendline team from building and testing Spendline's proxy, combined with public sources: adoption figures from CloudZero's State of AI Costs research; model pricing from Anthropic's published price list (illustrative rates; check current prices before relying on them); tool descriptions from each vendor's public documentation. The three-route comparison is our categorization judgment. Spendline's headers and supported routes were checked against the product on 23 October 2026.
See what this would look like in your product.
Start with a guided 30-day free pilot on live production traffic. The 30 days start when your traffic flows through Spendline, not at sign-up. We agree the scope, success criteria and paid terms before you start. There is no Spendline subscription fee during the pilot; your model-provider charges still apply.
Prefer email? fida@spendline.ai