Guide
Langfuse Alternatives: Tracing, Evals, and Who Can Actually Stop Spend
A fair comparison of Langfuse alternatives for tracing and evals, and which tools can check an AI budget before the provider call as well as alert on cost.
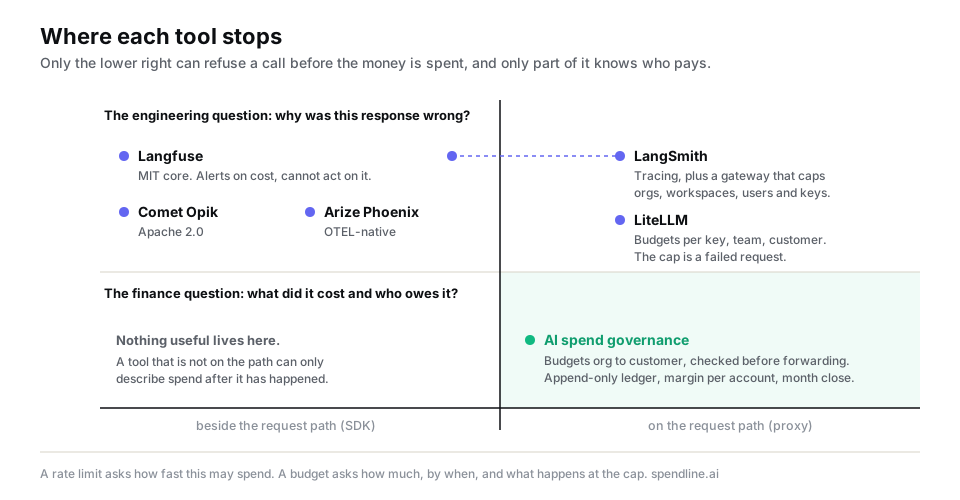
The short answer: if you want a like-for-like replacement for Langfuse, look at Comet Opik and Arize Phoenix, both open source and both self-hostable. If you are shopping because Langfuse showed you a cost number you did not like and you now want something that can act on it, look at tools on the request path. A tracing SDK sits beside it, so refusing a call needs a gateway or proxy, and several of those already have budgets.
We sell in that second category, so read this with that in mind. Every claim below is checkable against a primary source, and we say plainly where Langfuse or one of its alternatives is the better buy.
Why people go looking
Langfuse is not in trouble. It is actively developed, MIT licensed for every core product feature including tracing, evaluations, prompt management, experiments, annotation, and the playground, with only SCIM, audit logging, and data retention policies held back as paid enterprise add-ons. That is one of the more generous open source positions in this category, and it removes the usual reason to leave.
So the searches that lead here are mostly one of three:
- Price at volume. Langfuse Cloud starts free at 50,000 units a month, then Core at $29 a month, Pro at $199, and Enterprise at $2,499, with usage above the included allowance billed per 100,000 units. Tracing is priced by how much you trace, so the bill grows with exactly the thing you are trying to watch.
- A different technical taste. Teams standardizing on OpenTelemetry often prefer Phoenix; teams already inside Comet or LangChain often prefer Opik or LangSmith.
- A question tracing cannot answer. Someone asked what a specific customer costs, or asked for the spending to stop at a number, and traces do not do either.
The first two are shopping. The third is a category error, and it is the expensive one, because you can migrate between observability tools for a year without getting closer to an answer.
What Langfuse does well, stated fairly
Langfuse is an LLM engineering platform: traces and spans across an agent run, versioned prompt management, datasets and experiments, automated and human evaluation, annotation queues, and a playground. Token and cost tracking is attached to each observation, so you can see what a trace cost and slice it by model, environment, tag, or user.
It also alerts on cost, which is more than many of its peers. Langfuse alerts evaluate metrics over a window, including cost aggregations, and route notifications to Slack, a webhook, or GitHub Actions. Separately, spend alerts watch your own Langfuse subscription invoice against a threshold you set.
That is useful, and its documentation presents it as notification rather than a limit. Which is not a criticism. Langfuse sits beside the request path as an SDK, so it is not positioned to refuse a call.
Alerts and limits do different jobs
This is the distinction the whole comparison turns on, so it is worth being concrete.
An alert fires after the tokens are bought. For a slow drift in monthly spend that is fine, because a human can act inside the feedback loop. For the failure that actually hurts it is useless: a retry loop or a runaway agent burns hundreds of dollars in minutes, and a notification at the 80% line describes an event that has already finished.
Enforcement is a different shape. The budget is evaluated before the request is forwarded, and reaching the cap has a defined consequence:
org "acme-inc"                 $9,000 / month   alert at 80%, refuse at 100%
├─ team "support-ai"           $4,000 / month   alert at 80%, refuse at 100%
│   └─ agent "ticket-triage"     $900 / month   refuse at 100%
└─ customer "cust_4821"          $250 / month   alert only
Two properties of that tree are doing the work. Every level is checked in the request path, so the tightest binding scope wins before the provider is called, from an estimate of the request's cost. And the last line is a customer, the paying account, which tracing tools usually model as a user or a tag. The mechanics, including the check-then-act race that makes naive versions overspend under concurrency, are worked through in LLM budget enforcement.
The comparison
The table records what each vendor's documentation described when we checked it. "Not described" means we did not find it, not that the product cannot do it.
| Langfuse | Comet Opik | Arize Phoenix | LangSmith | LiteLLM | Spendline | |
|---|---|---|---|---|---|---|
| Primary job | Tracing, prompts, evals | Tracing and agent testing | OTEL-native tracing and evals | Tracing plus an LLM gateway | Self-hosted multi-provider proxy | Customer cost records and budget checks |
| Open source | MIT core, EE add-ons | Apache 2.0 | Elastic Licence 2.0 | No | Yes | No; hosted proxy, not self-hosted |
| Sits on the request path | No, SDK beside it | No | No | Gateway: yes | Yes | Yes, for supported routes |
| Cost caps | Alerts | Not described | Not described | Spend caps per org, workspace, user, key | Budgets per key, user, team, model, customer, with pre-call reservations | Budgets at org, team, agent and customer level |
| Behaviour at the limit | Notify | Not applicable | Not applicable | Fallback model | Request fails | Strict budgets refuse with HTTP 402; others alert |
| Cost against revenue per customer | Not described | Not described | Not described | Not described | Not described | Where you share revenue data |
| Month-end records | Not described | Not described | Not described | Not described | Not described | Closed months; invoice-total comparison filed as one adjustment |
| Public entry price | Free, Core $29/mo | Free, Pro $19/mo | Free, self-hosted | $0 dev seat, Plus $39/seat | Free, self-hosted | Guided pilot; terms agreed before you start |
Two rows carry most of the decision. "Sits on the request path" determines whether a tool can refuse a call before the money is spent. "Action at the cap" determines whether that refusal is useful to you. The rest is preference and price.
Three entries deserve more than a table cell.
LangSmith has quietly become the serious answer on this axis. Its LLM Gateway is a proxy: you swap the base URL and keep the rest of your code, and it sets spending caps for organizations, workspaces, users, and API keys, monitors spend at each level in real time, and can trigger a fallback model when a limit is violated. Anyone claiming the tracing vendors cannot enforce anything has not read that page. The honest limit is the scope list: organizations, workspaces, users, and keys are all internal units. None of them is the account that pays you, so it governs your engineering org rather than your customer base. Pricing is per seat, $0 for a single developer seat and $39 for Plus.
LiteLLM has the broadest budget scopes of the open source options, including an end-customer scope: max_budget with a budget_duration, set globally or per key, user, team, team member, model, or customer, with each request's estimated cost reserved before forwarding and rejected if it would exceed the budget, per its documentation checked on 23 October 2026 (this needs the database-backed deployment). If you want to run the in-path route yourself, it is the obvious starting point.
Opik and Phoenix are the true like-for-like swaps. Opik is Apache 2.0, self-hostable on the same codebase as the cloud product, free for 25,000 spans a month and $19 a month for Pro. Phoenix is OpenTelemetry-native under the Elastic License 2.0 and free to self-host. Neither adds cost control, and neither claims to.
What the finance question actually needs
If you moved to a tracing tool and still cannot answer finance, check three properties.
Coverage. Instrumentation is something each code path has to remember. A new microservice, a cron job, or a batch script that calls the provider directly never appears, and nothing tells you it is missing. An in-path proxy narrows this for the traffic routed through it, but it does not see direct calls either. Either way, compare your recorded total with the provider invoice to size the gap.
The grouping is wrong. Tracing tools model a user or a session. Finance needs the paying account, which is the join key to revenue. A tag can approximate it, but an optional tag is not a contract, and margin work needs cost per customer to be complete rather than mostly complete.
Traces are not a ledger. Trace stores have a retention window (30 days on the Langfuse free tier, 90 on Core, as of September 2026). A finance record is append-only, so corrections are new rows rather than edits, and it survives past the period it describes because someone will reopen it. That record is what gets compared against the provider invoice at month end and locked when the period closes, a workflow covered in the AI month close.
None of this makes observability tools bad. It makes them a different product answering a different question, which is how their own documentation presents them. Where each layer stops is mapped in gateway vs. observability vs. governance.
What a migration actually costs
The part that breaks quietly is attribution. Observability identifiers are optional metadata; governance identifiers are billing inputs. Map them deliberately rather than by search and replace, and set them server-side, because an identifier accepted from the client is a spoofable input to a number you will invoice on.
| What it identifies | Langfuse | Spendline |
|---|---|---|
| The paying account | metadata tag or userId |
x-customer-id |
| The agent or feature | tags or trace name |
x-agent-id (one stable value per agent) |
| One user action's fan-out | sessionId or trace grouping |
x-workflow-id |
| Cost centre | metadata tag |
x-spendline-tags with a cost_center or team key |
| Platform auth | SDK public and secret keys | x-spendline-key |
The integration itself is a base URL change plus metadata injection for full attribution:
import OpenAI from "openai";

const client = new OpenAI({
  baseURL: "https://www.spendline.ai/v1",
  apiKey: process.env.OPENAI_API_KEY,
  defaultHeaders: {
    "x-spendline-key": process.env.SPENDLINE_API_KEY,
  },
});

const response = await client.chat.completions.create(
  { model: "gpt-5.2", messages },
  {
    headers: {
      "x-customer-id": account.id,        // the paying account, set per request server-side
      "x-agent-id": "support-summarizer", // stable per agent
      "x-workflow-id": run.id,            // groups this run's calls
    },
  }
);
Keeping both is the normal outcome, and it is not redundancy. Tracing answers why a response was wrong; the ledger answers what it cost and who owes it. They are not competing for the same seat.
Common failure modes
- Migrating for the licence, then discovering the gap. Moving from Langfuse to Opik changes your licence and your bill. It does not get you a cap, because neither documents one.
- Treating an alert as a control. An 80% notification on a monthly budget cannot stop a retry storm that completes in four minutes. The controls that stop a single run work on the run, not the month.
- Trusting tags for billing. Optional metadata set by whichever code path remembered it leaves an unattributed pool. Measure it.
- Capping keys and calling it customer governance. Key and workspace limits protect your infrastructure. They say nothing about whether a specific account is profitable.
- Letting retention quietly delete the evidence. A 30-day window is fine for debugging and short of what a reconciliation and close cycle needs.
How Spendline fits
Spendline is a hosted proxy on the request path. Point a supported route's base URL at Spendline and send x-customer-id per request from your server's own context; Spendline records the supplied customer ID and server time with each routed call, prices it, and writes it to an append-only ledger across OpenAI, Anthropic and eight other providers. Spendline checks configured budgets before forwarding supported requests. Strict budgets reject requests whose estimated cost would exceed a limit. Actual response cost can differ from the estimate. Where you share revenue data, it compares customer revenue with attributed AI cost over the same period; other delivery costs are not included. Calls sent directly to a provider are outside its records.
It is not a tracing tool and does not try to be. If you need to debug a bad agent response, keep Langfuse.
FAQ
What are the closest open source alternatives to Langfuse? Comet Opik (Apache 2.0, same codebase self-hosted as cloud) and Arize Phoenix (OpenTelemetry-native, Elastic License 2.0). Langfuse's own core is MIT licensed, so licensing alone is rarely the reason to move.
Can Langfuse enforce a spending limit? Its documentation describes alerts, not limits: cost alerts to Slack, a webhook, or GitHub Actions, and alerts on your own subscription invoice. It sits beside the request path, so it is not positioned to refuse a call.
Does LangSmith enforce budgets? Yes, within its own scopes. Its LLM Gateway is a proxy that caps spend per organization, workspace, user, and API key and can fall back to another model at the limit. None of those scopes is your paying customer.
Should we replace Langfuse or add to it? Usually add. Tracing answers why a response was wrong, which is a useful job and a different one from what finance asks.
What does an observability tool miss that finance needs? A way to see which traffic is missing, grouping by the paying account rather than the user or session, and records kept and corrected with new entries that finance can compare with the invoice at month end.
Sources and method
Written by the Spendline team, combined with public primary sources, checked on 22 September 2026 unless stated: plans and prices from Langfuse pricing, Comet pricing, and LangChain pricing; licensing from Langfuse's open source page, the Opik repository, and the Phoenix repository; alerting behaviour from Langfuse's alerts documentation; gateway behaviour from LangSmith's LLM Gateway page; budget scopes from LiteLLM's proxy documentation. Vendor prices change without notice, so check each page before relying on a figure. The two-axis categorization and the judgment about which gaps are structural rather than incidental are ours. Langfuse's homepage (no change of ownership noted), LiteLLM's budget documentation and Spendline's own behaviour were re-checked on 23 October 2026.
See what this would look like in your product.
Start with a guided 30-day free pilot on live production traffic. The 30 days start when your traffic flows through Spendline, not at sign-up. We agree the scope, success criteria and paid terms before you start. There is no Spendline subscription fee during the pilot; your model-provider charges still apply.
Prefer email? fida@spendline.ai