Guide
Helicone Alternatives for Teams That Need Financial Governance
What Helicone does, what its status looked like on 23 October 2026, and a fair look at the alternatives, including which ones can check a budget before the provider call.
The short answer: if you used Helicone for tracing, prompts, and evaluation, the closest replacements are Langfuse and Arize Phoenix. If you used the gateway half for multi-provider routing and rate limits, look at LiteLLM and Portkey. And if the reason you are shopping is that finance wants cost per customer, budgets checked before the call, and month-end records, compare what each option's documentation describes, because some gateways cover part of that. This guide maps all three.
We sell in the third category, so read the comparison with that in mind. Every factual claim below is checkable against a primary source, and we say plainly where an observability tool is the better buy.
Why teams are looking in the first place
In March 2026 Mintlify announced it was acquiring Helicone. Helicone's own post said its services would stay live in maintenance mode, with security updates, new models and bug fixes continuing, and Mintlify said it would support customers who wanted to migrate.
That is no longer the whole story. When we checked on 23 October 2026, Helicone's homepage said Helicone is no longer part of Mintlify, with details to come. We do not know what that means for its roadmap, and we would rather say so than guess. The open source repository is still available under the Apache 2.0 licence, so self-hosting remains an option.
So the honest reason to move is not the news. It is a requirement Helicone does not meet for you, which makes this a good moment to write down what you needed it to do.
What Helicone does well, stated fairly
Helicone is an LLM observability platform with an AI gateway attached, and it is good at both: request logging and dashboards, sessions and segmentation, prompt management, datasets, a playground, alerts, and a query language over your own request data. Pricing is public, with retention and ingestion rate stepping up per tier: a free Hobby tier at 10,000 requests a month, Pro at $79 a month, Team at $799, and custom enterprise terms.
It also does more cost control than most observability tools. Helicone's custom rate limits accept a policy header in the form [quota];w=[window];u=[unit];s=[segment], and the unit can be cents instead of requests. So 100;w=3600;u=cents;s=user caps a user at one dollar an hour. That is real spend control, it works through the gateway rather than async logging, and any comparison that claims observability tools cannot limit spend at all is wrong.
The distinction that matters is narrower, and it is the subject of the rest of this guide.
A rate limit is not a budget
A rolling window quota answers "how fast may this spend?" A budget answers "how much may this cost, in total, this month, and what happens at the cap?" They look similar and behave completely differently.
Take an agent product with 40 customers and a $9,000 monthly AI cost target. A limit of one dollar per hour per user is, at 40 customers running continuously, an implicit ceiling near $28,800 a month, and it never tells you that. It also has no view of the month: a customer that idles for three weeks then runs hard for four days stays inside every rolling window while blowing the plan for that account. The ceiling exists only per segment, so the organisation total is whatever the arithmetic happens to produce.
A budget is the other shape entirely:
org "acme-inc"                 $9,000 / month   alert at 80%, refuse at 100%
├─ team "support-ai"           $4,000 / month   alert at 80%, refuse at 100%
│   └─ agent "ticket-triage"     $900 / month   refuse at 100%
└─ customer "cust_4821"          $250 / month   alert only
Each level is checked before the request is forwarded, the tightest binding scope wins, and each budget has a defined behaviour at its limit. A pre-call check works from an estimate, so a long response can still settle above a cap. The scopes, the available actions, and the concurrency trap that makes naive implementations overspend are worked through in LLM budget enforcement.
The comparison
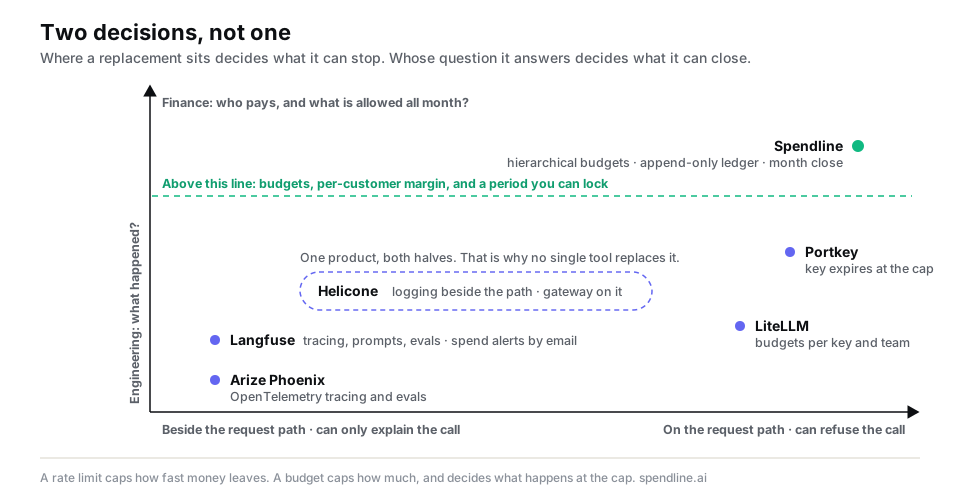
The table records what each vendor's documentation described when we checked it. "Not described" means we did not find it, not that the product cannot do it.
| Langfuse | Arize Phoenix | LiteLLM | Portkey | Spendline | |
|---|---|---|---|---|---|
| Primary job | Tracing, prompts, evals | OTEL-native tracing and evals | Self-hosted multi-provider proxy | Managed AI gateway | Customer cost records and budget checks |
| Open source | Yes, self-hostable | Yes, Elastic Licence 2.0 | Yes | Core gateway | No; hosted proxy, not self-hosted |
| Sits on the request path | No, SDK beside it | No | Yes | Yes | Yes, for supported routes |
| Cost caps | Cost alerts | Not described | Budgets per key, user, team, model, customer, with pre-call reservations | Budget limits on provider integrations, cost or token | Budgets at org, team, agent and customer level |
| Behaviour at the limit | Notify | Not applicable | Request fails | Key expires | Strict budgets refuse with HTTP 402; others alert |
| Cost against revenue per customer | Not described | Not described | Not described | Not described | Where you share revenue data |
| Month-end records | Not described | Not described | Not described | Not described | Closed months; invoice-total comparison filed as one adjustment |
| Public entry price | Free tier, Core $29/mo | Free, self-hosted | Free, self-hosted | Free tier | Guided pilot; terms agreed before you start |
Two rows carry most of the decision. "Sits on the request path" decides whether a tool can refuse a call before the money is spent; "behaviour at the limit" decides whether the refusal is useful. Everything else is preference.
The cost-cap row deserves detail. LiteLLM has the broadest budget scopes of the open source options: max_budget with a budget_duration, set globally or per key, user, team, team member, model, or end customer. Its documentation (checked 23 October 2026) says it reserves each request's estimated cost before forwarding and rejects a request whose reservation would exceed the budget; budgets need a database-backed deployment. Portkey sets cost or token limits on provider integrations, resetting weekly, monthly, or not at all, and expires the key at the limit; it is on the enterprise plan and select Pro accounts. Langfuse alerts on cost metrics to Slack, a webhook, or GitHub Actions, and separately watches your own Langfuse invoice; both are monitoring rather than a control, and it says so. That trade-off, and the alternatives to Langfuse itself, are worked through in Langfuse alternatives.
Migrating the attribution, not just the traces
The part of a migration that quietly breaks is the metadata. Helicone attribution rides on its own headers, and everything downstream (per-customer numbers, margin analysis, month end) is built on those identifiers. Map them deliberately rather than by search and replace.
| What it identifies | Helicone header | Spendline header |
|---|---|---|
| The paying account | Helicone-User-Id (or a custom property) |
x-customer-id |
| The agent or feature | Helicone-Property-Feature |
x-agent-id (one stable value per agent) |
| One user action's fan-out | custom property | x-workflow-id |
| Cost centre | custom property | x-spendline-tags with a cost_center or team key |
| Platform auth | Helicone-Auth |
x-spendline-key |
The integration itself stays a base URL change plus metadata injection:
import OpenAI from "openai";

const client = new OpenAI({
  baseURL: "https://www.spendline.ai/v1",
  apiKey: process.env.OPENAI_API_KEY,
  defaultHeaders: {
    "x-spendline-key": process.env.SPENDLINE_API_KEY,
  },
});

const response = await client.chat.completions.create(
  { model: "gpt-5.2", messages },
  {
    headers: {
      "x-customer-id": account.id,          // the paying account, set per request server-side
      "x-agent-id": "ticket-triage",        // stable per agent
      "x-workflow-id": run.id,              // groups this run's calls
    },
  }
);
One rule survives every migration: set customer IDs on your server from authenticated request context, and never in a shared client's default headers. Spendline records the supplied customer ID and server time; it cannot tell a wrong customer ID from a right one. The full metadata contract is in how to track LLM costs per customer.
Where this connects to the close
Enforcement and reconciliation are the two things that turn cost data into an accounting record, and they are the reason a governance layer exists at all next to a perfectly good observability tool.
Budgets checked before the provider call make a runaway agent an in-flight problem with an in-flight answer rather than a line item you find on the fifteenth. An append-only ledger keeps corrections as new rows. At month end the ledger is compared against the OpenAI and Anthropic invoices, gaps are investigated, adjustments are posted, and the period is closed so the number stops moving. In Spendline the invoice step is a total-level comparison filed as one adjustment; investigating the cause of a gap stays with your team. That workflow is described in the AI month close, and where each layer stops is mapped in gateway vs. observability vs. governance.
Common failure modes when migrating
- Replacing like for like without asking why. A service that still does what you need may be fine for a while yet. Migrate for a requirement.
- Losing the tag history. Export before you cut over. A January to September per-customer series with a gap in it is not a series.
- Assuming one tool covers both halves. Most replacements are observability or gateway, not both, and teams that plan for one discover the other three weeks later.
- Treating a rate limit as a cap. Covered above, and the most expensive misreading in this category.
- Leaving a side door open. A batch job, or a fallback that calls the provider directly, appears in no in-path tool's numbers. Route those paths too, or account for them separately.
- Client-set identifiers. They survive migrations because nobody re-reads them, and they corrupt every budget window downstream.
FAQ
What is Helicone's current status? Mintlify announced an acquisition in March 2026 and Helicone said it would continue in maintenance mode. On 23 October 2026 Helicone's homepage said it is no longer part of Mintlify, with details to come, so confirm its roadmap with Helicone directly. The repository is still available under Apache 2.0.
What is the closest replacement for Helicone? It depends which half you used. Langfuse and Arize Phoenix for tracing, prompts, and evaluation; LiteLLM and Portkey for the gateway. No single product replaces both halves, so plan for two.
Can Helicone enforce a spending cap? Partially. Its cost-based rate limits set a quota in cents over a rolling window, segmented globally, per user, or per custom property, through the gateway integration. That caps a rate of spend rather than a monthly total across an organisation and its customers.
Do observability tools track cost per customer? Through optional tags, which is useful for debugging and weak for accounting. They model the session or end user rather than the paying account, and nothing flags a code path that forgot the identifier.
Should we migrate off Helicone right now? Not urgently. Move when you hit a requirement it does not meet for you: a monthly budget checked before the provider call, cost against revenue per customer, or month-end records for finance.
Sources and method
Written by the Spendline team. The March 2026 acquisition announcements are Mintlify's and Helicone's; Helicone's current status statement is from its homepage, checked on 23 October 2026. Helicone's features, tiers, and rate limit behaviour come from its pricing page, its rate limits documentation, and its repository, all checked in September 2026. Budget behaviour for other tools comes from their own docs: LiteLLM, Portkey, Langfuse, and Arize Phoenix. Vendor features and prices move; check them before deciding. The two-axis framing and the rate-limit-versus-budget distinction are our categorisation judgment, not anyone's published position. LiteLLM's budget documentation and Spendline's own behaviour were re-checked on 23 October 2026.
See what this would look like in your product.
Start with a guided 30-day free pilot on live production traffic. The 30 days start when your traffic flows through Spendline, not at sign-up. We agree the scope, success criteria and paid terms before you start. There is no Spendline subscription fee during the pilot; your model-provider charges still apply.
Prefer email? fida@spendline.ai